How not to drown in AI?

Everyone is talking about productivity tools, but few are questioning the very source of this pressure to perform: social networks and always-on connected devices, hungry for fresh content 24/7. What if, as Chris Moran from The Guardian suggests, the point was not to produce more, but to produce differently? Less journalism, but more service. Instead of using AI to flood the world with content, why not use it to reduce the volume and increase relevance? A deliberate shift toward editorial restraint. And what if the chatbots of fifteen years ago—based on simple decision trees—were actually better suited to journalism than today’s hallucinatory foundation models?
In his opening session, Nic Newman stated: “With AI, we do not yet know what the product is. We need to experiment together and find the value, drawing on our core mission.” And that is precisely the paradox: newsrooms, already short on time, should now be devoting more of it than ever to testing, exploring, and feeling their way forward.
When “journalists believe that language belongs to them” (Lucy Kueng), the rise of large language models inevitably calls their role into question. Who creates meaning? Who edits what? And with what intent?
In this new artificial world, “digital doubt is becoming the new normal.”
Today, technology is the easy part. What drains energy now is editorial validation. You need to be able to define what makes “good content” in order to teach it to AI. The Guardian shares a failure rather than a success: automatic summarisation during live coverage. “Fine-tuning takes a hell of human effort!” It is not enough to teach the machine what is accurate — you must also teach it what is important. Yet the machine tends to prefer what is viral. Chris Moran almost jokes that he would send the two Notebook LM podcasters to the moon, tired of the relentless hype cycle. Still, he acknowledges the usefulness of very specific features, like jumping directly to a relevant passage in a PDF. In his view, AI will mediate everything — devices, platforms — and it will be “good enough” for the general public. His message to newsrooms: “Please, do not reinvent the same tools.”
Reminder: LLMs are Large Language Models, not Large Fact Models. Truth is deterministic, not probabilistic.
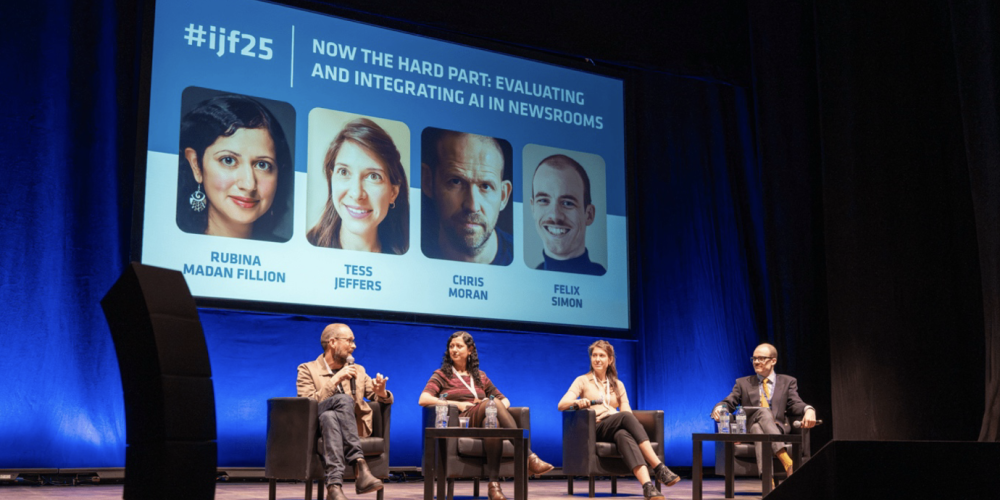
Ezra Eeman, Director of Strategy and Innovation at NPO, raises the question: should we simply optimise the process, or completely rethink it in loops, where the audience is no longer the end point but the core of the system? The public is no longer just looking for information — it wants answers. And every platform, from search engines to social networks to voice assistants, has become a machine designed to deliver those answers. The very format of the article is gradually fading, giving way to conversational, adaptive, and instantaneous forms.
Spotify has moved from playlists to daylists. Deepfakes have become a cultural standard. And it is not the C2PA — designed to flag AI-generated content — that will solve this growing opacity. While the tech industry views it as a technical transparency tool, media organisations project onto it a near-symbolic hope: that of making the human visible again (again, according to Ezra Eeman).
For newsrooms, the challenge is clear: avoid getting lost in “fancy experiments” based on “messy data”. Here, AI-native newsrooms like India’s Scroll have a clear advantage. Its head of the AI Lab for News, Sannuta Raghu, explains how AI (always with a human in the loop) enables them to produce up to 20 videos a day in a country with 22 official languages, where search is predominantly voice-based.
For Joseph El Mahdi, News Commissioner at Swedish Radio, high-quality journalism and AI-generated content are fundamentally incompatible. However, SR’s news strategy does integrate AI assistance: transcriptions, headline suggestions, and the handling of large volumes of data. A tool like “Vinkelkompisen” – the angle buddy – supports the editorial process, while their chatbot developed with the EBU’s Neo is deliberately limited to prevent the spread of fake news.
At Semafor, Gina Chua sees a clear opportunity to improve audience engagement through AI: integrating related articles, summaries, and alternative perspectives to anticipate audience reactions and reflect diverse viewpoints. Khalil Cassimally from The Conversation sees these tools as a way to better understand audiences, thanks to easier access to audience insights. Anyone can now build their own data analysis tool using vibe coding.
At The Wall Street Journal, generative AI is used to power specialist chatbots like Lars, a tax assistant. At The New York Times, a bot was developed after two months of focus groups with editorial teams. Two-thirds of the needs focused on summarisation, which led to the creation of Echo — capable of summarising any NYT URL. Echo 2.0 adds a layer of editorial judgment. Moreover, the NYT favours “tiny experiments as a concept”.
In most newsrooms, AI — whether predictive or generative — is now either integrated directly into the CMS or included in bespoke toolkits (the NYT is currently bringing together all its use cases into a unified interface).
On the topic of partnerships between big tech and the media, Ezra Eeman notes a clear slowdown. Karen Hao, an engineer trained at MIT and now a journalist at The Atlantic, reminds us that Silicon Valley’s technology has never been aligned with the public interest. In her view, newsrooms are partnering with OpenAI in the hope of positive outcomes — but she foresees a repeat of the social media scenario: asymmetrical relationships, followed by a sudden and ruthless ejection.
For Ezra Eeman, “It’s better to be inside than outside.” But Karen Hao, drawing on her research for Empire of AI, insists: the narrative of inevitable progress toward generative and general AI is a constructed one. Nothing is inevitable. And partnering with companies that, in her view, are accelerating the death of journalism may not be the wisest strategic move for newsrooms. Her training series for The AI Spotlight, produced with the Pulitzer Center, will be available for free later this year.
A practical takeaway: models age quickly. They need to be retested and re-evaluated regularly — a costly, time-consuming process that clashes with the daily pace of newsroom operations. The Wall Street Journal has even created a dedicated workflow editor role to monitor this cycle of obsolescence.
A question from the audience: should we use generative AI or not? The answer was nuanced: yes, if the use case does not require extreme precision and does not involve direct contact with the public. No, if the stakes are critical and high-risk.
All of this underpinned by a slogan as appealing as it is illusory: Move fast without breaking things. But perhaps, now more than ever, it is time to break a few certainties.
And for now, as David Caswell points out, no one is making money from generative AI — not even the model providers like OpenAI or Anthropic, who are investing far more than they are earning.
Some of the facts highlighted by Karen Hao: in 2023, one of the most widely used datasets for training generative image AIs was found to contain child sexual abuse material. The Apollo program is estimated to have cost, in today’s value, around $300 billion over 15 years to land humans on the Moon. By contrast, $500 billion will be spent in just four years… just to build bigger chatbots.
Originally, AI research was conducted in universities, publicly funded, and driven by goals of efficiency. Today, it is led by private companies, self-financed, with unlimited access to data and enormous computing power — guided primarily by a hunger for market domination. Faster, larger, and always more.
Let us hope journalism does not become generative AI’s edge case scenario — the exception that proves the rule, sidelined by Big Tech’s relentless expansion.


